

- What fast search does, and why it isn’t the whole answer
- What re-ranking is, and how it fits after a fast search step
- How TypeSafe scores one candidate against a query, and how much that improves the result
Try it yourself
Open a query, candidate, and re-ranking question in the TypeSafe PlaygroundHow do we find one document in thousands?
You have a pile of documents, and a query, a piece of text describing what you’re looking for. Somewhere in the pile is the one document that answers it. Checking every document against the query one at a time works, at one comparison per document: millions of documents means millions of comparisons per query. You can improve performance with a two-step approach:- Cut the pile down to a short list of likely candidates, using a method fast enough to run on the whole pile.
- Apply a more accurate step to that short list, to find the exact right answer.

What is fast search?
Fast search is any method that can compare a query against every document in a large corpus and quickly return a ranked shortlist. Common methods include keyword search, such as BM25, and dense embeddings, which compare passages by meaning. Systems often combine both methods. The first step here is BM25 and nothing else. BM25 ranks passages by shared words. Keeping this step simple leaves the attention on re-ranking, which is the point of the cookbook. The choice of fast search method is a side issue: re-ranking only ever sees the passages that make the shortlist.What is re-ranking?
Re-ranking takes the shortlist fast search already produced and puts it in a better order. Instead of comparing the query against the whole corpus at once, it compares the query against each candidate on the shortlist individually, and sorts the shortlist by that score.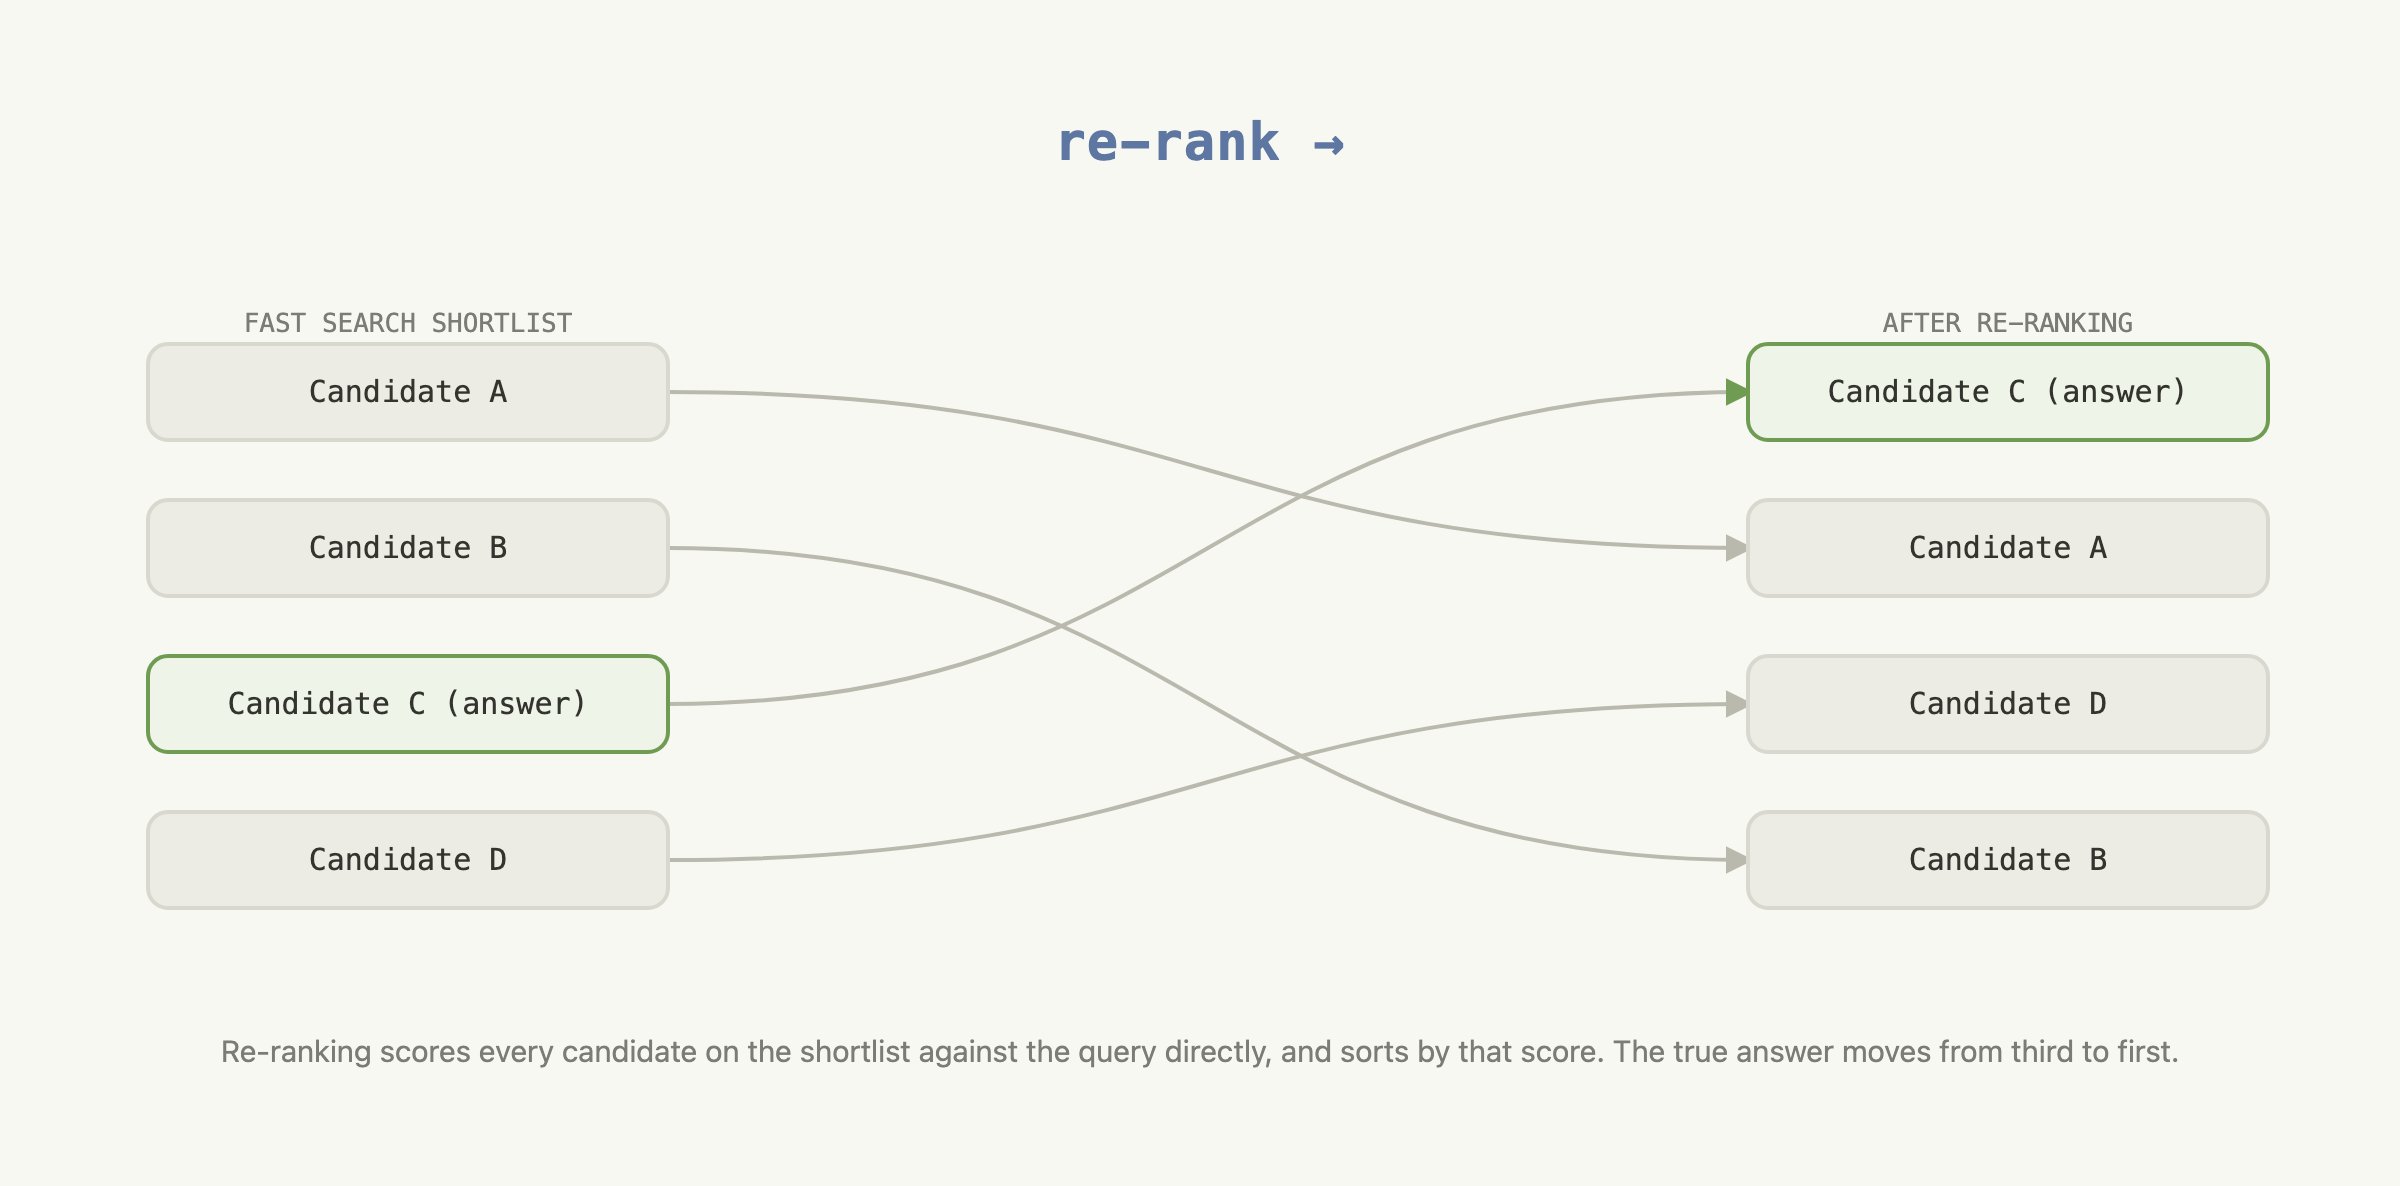
Re-ranking with TypeSafe
A re-ranker needs a comparable score for every query-candidate pair. A general-purpose language model can produce these scores, or rank the whole shortlist directly. For independent pair scoring, however, you need to define a scoring scale and prompt the model to apply the same standard to every candidate. Repeated calls can still produce different scores for the same pair, while general-purpose generation adds time and cost to a task that only needs one number.What TypeSafe returns
With TypeSafe, the scoring request can remain a yes/no question:Noul instead
returns a number between 0 and 1, called a
noul. The noul is TypeSafe’s estimate
of how likely the answer is to be yes.
The question’s criteria define what counts as true and false. TypeSafe applies them to
every query-candidate pair and returns the noul directly. That noul is the score the
application sorts on. No scoring scale has to be invented for a general-purpose model, and
TypeSafe is built to do this repeated scoring faster, cheaper, and more consistently.
In simplified pseudocode, one TypeSafe scoring call looks like this:
A re-ranking example
Fast search and re-ranking now run on CLERC, a legal retrieval dataset. This example uses 3,565 court opinion passages and 40 queries.Setup
The first step installs the packages this walkthrough depends on.bm25sanddatasetsbuild the fast search shortlist.typesafe-sdkandcooksafehandle re-ranking and API caching.matplotlibdraws the result charts.
TYPESAFE_API_KEY.
Ranking the passages with fast search
The dataset used here is a corpus of US court opinions, 170 rows pooled together. Each row breaks down like this:- Query: an opinion excerpt with a citation removed.
- Gold: the passage the removed citation pointed to, the one correct answer to the query.
- Candidates: every other passage in the corpus, each one something the query could be matched against by mistake.
- Load the corpus.
- Rank it against every query with BM25.
Fast search is unlikely to rank the right passage first
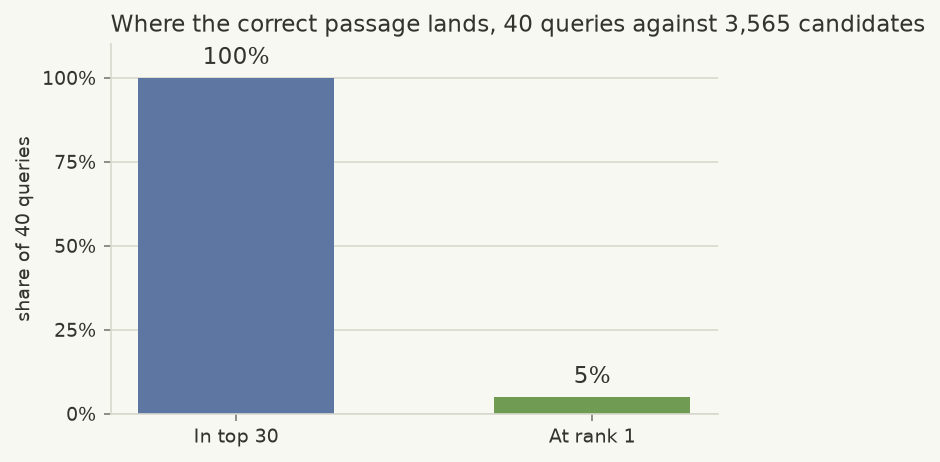
The chart shows where fast search puts the correct passage, out of 3,565 candidates. Fast search reliably narrows the corpus down to a shortlist that contains the right answer. It contains the right answer for 100% of the 40 queries. But that passage is rarely the top-ranked one on the shortlist, only 5% of the time. Re-ranking below only reorders the top 30 candidates already on the shortlist. It cannot add a passage that fast search did not select. Here, the shortlist contains the correct passage for all 40 queries, so re-ranking can focus on putting each one in a better position.Re-ranking it with TypeSafe
Re-ranking scores every candidate on the shortlist against its query, then sorts by that score. The question TypeSafe asks about each pair is whether the candidate could be the passage the query’s removed citation points to. The next cell does the following:- Define that question.
- Ask it once per candidate on every shortlist, 40 queries times 30 candidates, 1,200 calls in total, run concurrently instead of one after another.
- Sort each shortlist by the score TypeSafe returns, producing the re-ranked result.
Re-ranking moves the right answer toward the top
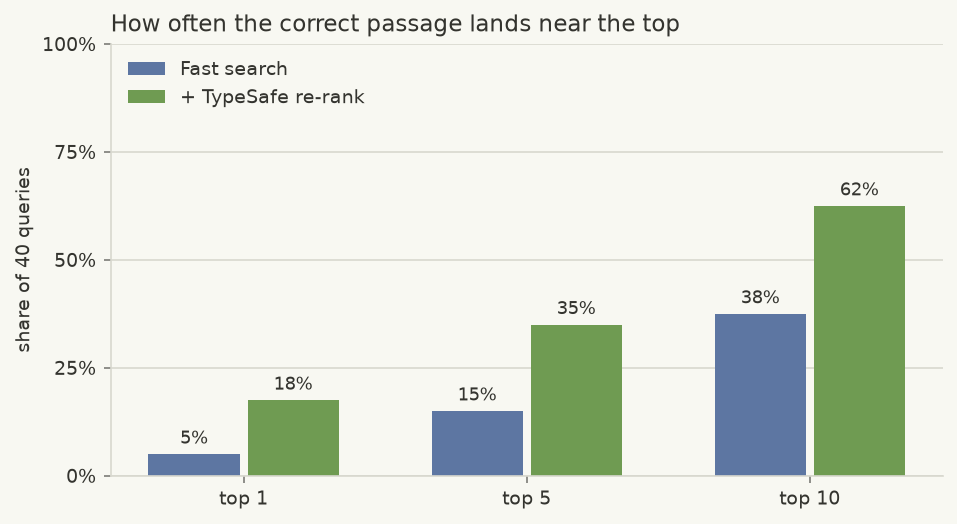
The chart compares fast search against fast search plus re-ranking, at three thresholds. Re-ranking moves the correct passage closer to the top at every one of them:- Top 1 — 5% → 18%
- Top 5 — 15% → 35%
- Top 10 — 38% → 62%
What’s next
The same building blocks show up elsewhere in TypeSafe’s docs:- Noul, for how TypeSafe turns a yes/no question into a score.
- Speculative Fan-Out, for asking several questions about one document in a single call.
- Line-by-line Search, for another way to search a corpus by meaning rather than keywords.