

- Overview
- big reasoning models extract structured data well, but are slow and expensive
- small models are cheap, but make mistakes
- a cascade gets most of the quality at a fraction of the cost
- the models we use, and their price ($ per 1M tokens, input / output; standard rates
checked September 15, 2026):
- rung 0 (mini):
gpt-5.4-miniat $0.75 / $4.50 - rung 1 (reasoning):
gpt-5.5at $5.00 / $30.00 (roughly 7x the mini) - verifier: TypeSafe
jev-1.12at $0.042 / $0.00 (output tokens are free; published Jev pricing)
- rung 0 (mini):
- Algorithm
- Extract with a cheap/small model.
- Verify with TypeSafe primitives: a per-field yes/no (“Noul question”)
question
- (e.g. “is this value absent from the source?”, “was it lifted from unrelated text?”), each returning P(something is wrong).
- Escalate to an expensive reasoning model if a verifier signal fires; otherwise keep the cheap answer.
- This Cookbook
- walks one real example end-to-end, then shows the tradeoff across 100 prompts
- note: the two extraction rungs use text-mode OpenAI
- we do not use structured outputs, tool calls, or json mode, because:
- a schema following mistake is not the mistake we expect an LLM to make (it’s easy to make synthetic data for this)
- if an LLM does fail to follow the schema, it’s almost always very confused, so constrained decoding doesn’t fix the underlying issue
- we encourage you to try them though!
Setup
- install the dependencies (the TypeSafe verifier client is served from TypeSafe’s package index):
- then set
OPENAI_API_KEYandTYPESAFE_API_KEYin your environment
Step 1: the data
We choose a huggingface dataset called scrapegraphai- This row is an NYU events-calendar page (“Fall 2024 Census Date”):
- the schema asks for just two fields:
registration_open_dateanddescription - the prompt scrape captured only calendar nav and boilerplate: there is no registration date, or description
- note the schema’s
descriptionfield even ships an example value (“Registration opens for the fall semester”) in its own field description
- the schema asks for just two fields:
- so a well-behaved extractor should decline to invent the fields the page doesn’t contain
- let’s see if the small model does the right thing!
Step 2: extract with the mini model (text mode)
- note:
gpt-5.4-miniis very stochastic on this input — even attemperature=0it invents a differentdescriptionon nearly every run. For a reproducible walkthrough we hard-code the one canonical fabrication the rest of this notebook explains (and that the verifier flags at P(wrong) > 0.8). A real pipeline would just takeextract(MINI, prompt, schema, content, temperature=0)directly.
- The record is schema-valid (the line above prints
True), yet it’s wrong:registration_open_dateis left blank, which matches the page: it states no date- but
descriptionis fabricated: the page never describes a registration date, so mini invents a plausible one. It may parrot the schema’s own example, “Registration opens for the fall semester”, or narrate “…was not found in the document” - a JSON-Schema check can’t see this. A cheap model produces confident, schema-satisfying fabrications of this kind, and catching them is the job of a semantic verifier
Step 3: verify with TypeSafe
- the verifier is TypeSafe; for each field we build a
Noulquestion:- a narrow yes/no, framed so that
true= something is wrong (escalate)
- a narrow yes/no, framed so that
- TypeSafe returns a calibrated
noul=P(true)per question, in one system_one call - the question set:
- one holistic
__overall__::judgehead (“should this record be escalated?”). We compute and display it to contrast a whole-record judgment with the per-field heads, but the gate in Step 4 does not use it — escalation is driven by the per-field battery. - a per-field battery
- non-empty fields get the full set of heads
- empty fields (null / "" / []) get only the
absence_wronghead
- (the full pipeline also has a
spurioushead for whole containers and an overalldifficultyscore; not shown here, to keep this walkthrough to the two gating heads)
- one holistic
- The TypeSafe Way: Decomposition
- Notice how everything is programmatically decomposed, this is TypeSafe way.
- Decomposition maximizes the intelligence of every prompt, and makes the algorithm tunable and interpretable.
-
Run the whole battery over the mini extraction
- TypeSafe concentrates the signal on the fields that are actually wrong.
- Our results are calibrated: high on the field that is wrong, low on the field that is correct, medium on a field that looks off without being clearly wrong
- This is what a typesafe verifier buys you over a blunt “is this whole thing good?” judge
Step 4: the escalation gate
- now we gate on
any_flag: escalate if any field flag exceedsFIRE_T(0.7, set above and shared with the<== FIRESmarker in Step 3) - this is a
max-style gate (escalate if any field fires), not a mean, so one confident red flag is enough instead of being averaged into silence
Step 5: escalate to the reasoning model
Since a signal fired, we pay for the strong model (gpt-5.5, reasoning_effort="high")
- The improvement
- The reasoning model drops the fabricated
description, returning"" - It recognized the page never describes a registration date, and declined to invent one
- The cascade turned a confident, schema-valid fabrication into an honest empty field
- And it only spent reasoning-model dollars on this one item because the verifier told it to
- The reasoning model drops the fabricated
Step 6: what this looks like on 100 prompts
- These are internal TypeSafe results, produced with the general method above:
- the same
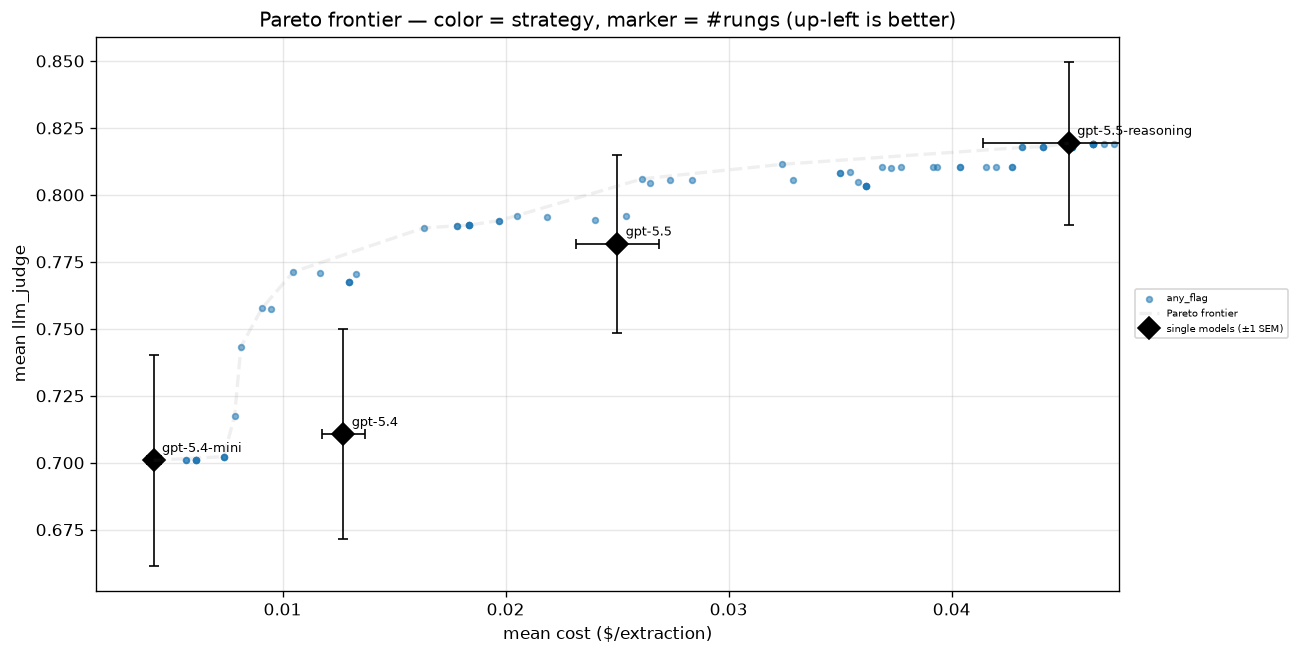
extract → verify → escalateloop,gpt-5.4-mini → gpt-5.5-reasoning,any_flaggate over the per-field heads, run over 100 scrapegraphai prompts - each item’s cheap-rung extraction is scored by TypeSafe; the gate threshold (“cut”) is swept 0→1, and every resulting config is plotted in (cost, quality) space
- the chart is a historical snapshot; its costs have not been recalculated at the current Jev rate listed above
- the same
- how to read it:
- black diamonds = the four models run on their own (cost climbs with capability; the
strongest,
gpt-5.5-reasoning, sits top-right at ≈0.81 quality for ≈$0.10/extraction) - blue points = the cascade at many gate thresholds; the dashed line is the pareto frontier
- the cascade frontier sits up-and-left of every single model: sweeping the gate buys you most of the top model’s quality at a fraction of its cost
- the cheap rung handles the easy items for near-free, and only the flagged items pay for the reasoning model
- black diamonds = the four models run on their own (cost climbs with capability; the
strongest,
Appendix A: what makes a good verifier signal
- the cascade is only as good as its verifier; what separates a useful signal from a
useless one:
- Narrow and grounded.
- one checkable yes/no about one field against the source (e.g. “is this value absent from the source?”), not a vague “is this extraction good?”
- vague questions give mushy, uncalibrated scores
- Bad = TRUE, with explicit criteria.
- frame each question so the escalate case is the
truecase, and state whattrue/falsemean
- frame each question so the escalate case is the
- Per-field, then aggregate with
max.- a per-field flag localizes the error and stays sparse and strong
max(“any flag fires”) ensures one confident red flag escalates, instead of being averaged into silence
- Independent and cheap.
- a dedicated verifier (here, TypeSafe) judging the output catches the extractor’s own blind spots
- it has to be cheap, or there are no savings left to capture
- Separating / calibrated.
- a good signal is high on real errors and low on correct ones, so a single threshold cleanly splits accept vs escalate
- that separation is what pushes the pareto curve up-and-left
- Narrow and grounded.