

The last two rows are the loop. One proposal call, with nothing to go on yet, gets to 1.87.
Four more rounds of reading its own worst predictions get to 1.77. Most of the gain is in
that first call, and how much the four rounds after it add is measured further down.
Setup
TYPESAFE_API_KEY and ANTHROPIC_API_KEY. Every API call is cached to
json_cache.json, which ships with the cookbook, so a re-render replays these numbers
without calling anything. Delete it to re-run live. The numbers came from TypeSafe
jev-1.12 and claude-sonnet-5 on 2026-08-03. propose() has a second branch for
gpt-5.6-luna, which was not run.
The first code cell is the whole implementation: API calls, encodings, metrics, chart
style. It is there so this file runs on its own, and the docs site folds it away. Skip it
on a first read - the recipe starts under it.
Two question types
A proposed question is one of two kinds, and the kind decides what number comes back.intensitybecomes aScore, for anything that comes in degrees. Its five levels are printed below, and the column is the average level, so a note that sits between “moderate” and “strongly” comes out between the two.presencebecomes aNoul, for a yes/no fact like whether a fault is named. The column is that one probability.
The method
The autoresearch loop
run_loop runs all five rounds and prints a block per round. An added question goes
straight in: its answers have already been fetched, and its importance will show later
whether it was worth asking. A revision or a drop takes away a column the model is already
using, so each one is tried first: refit with the change, and keep it only if the dev
error goes down. A refit costs no API calls, so trying a change and rejecting it is free.
Pointing it at your own data
PROPOSER_TASK is the only string that mentions wine, and featurize() takes any list of
strings. Editing that brief changes the proposal prompt, and the prompt is part of the
cache key, so the next run calls the API again for every round.
The request count grows with rows, not with questions: one request per row per round, so
100,000 rows is 100,000 requests a round. A revision counts as a new question, so it costs
another pass over every row. Raise the worker pool slowly. Eight is already enough to hit
a rate limit on a shared key.
What the questions see
Five held-out reviews, one at each quarter of the score range, against fifteen of the 38 questions: the top eight score questions by importance, plus the top seven nouls. Those fifteen rows are then sorted by which way the answer moves with the critic score. Questions whose answer rises with the score come first, questions whose answer falls with it come after the divider. So going left to right, from the worst review to the best, the answers above the divider should climb and the answers below it should drop off.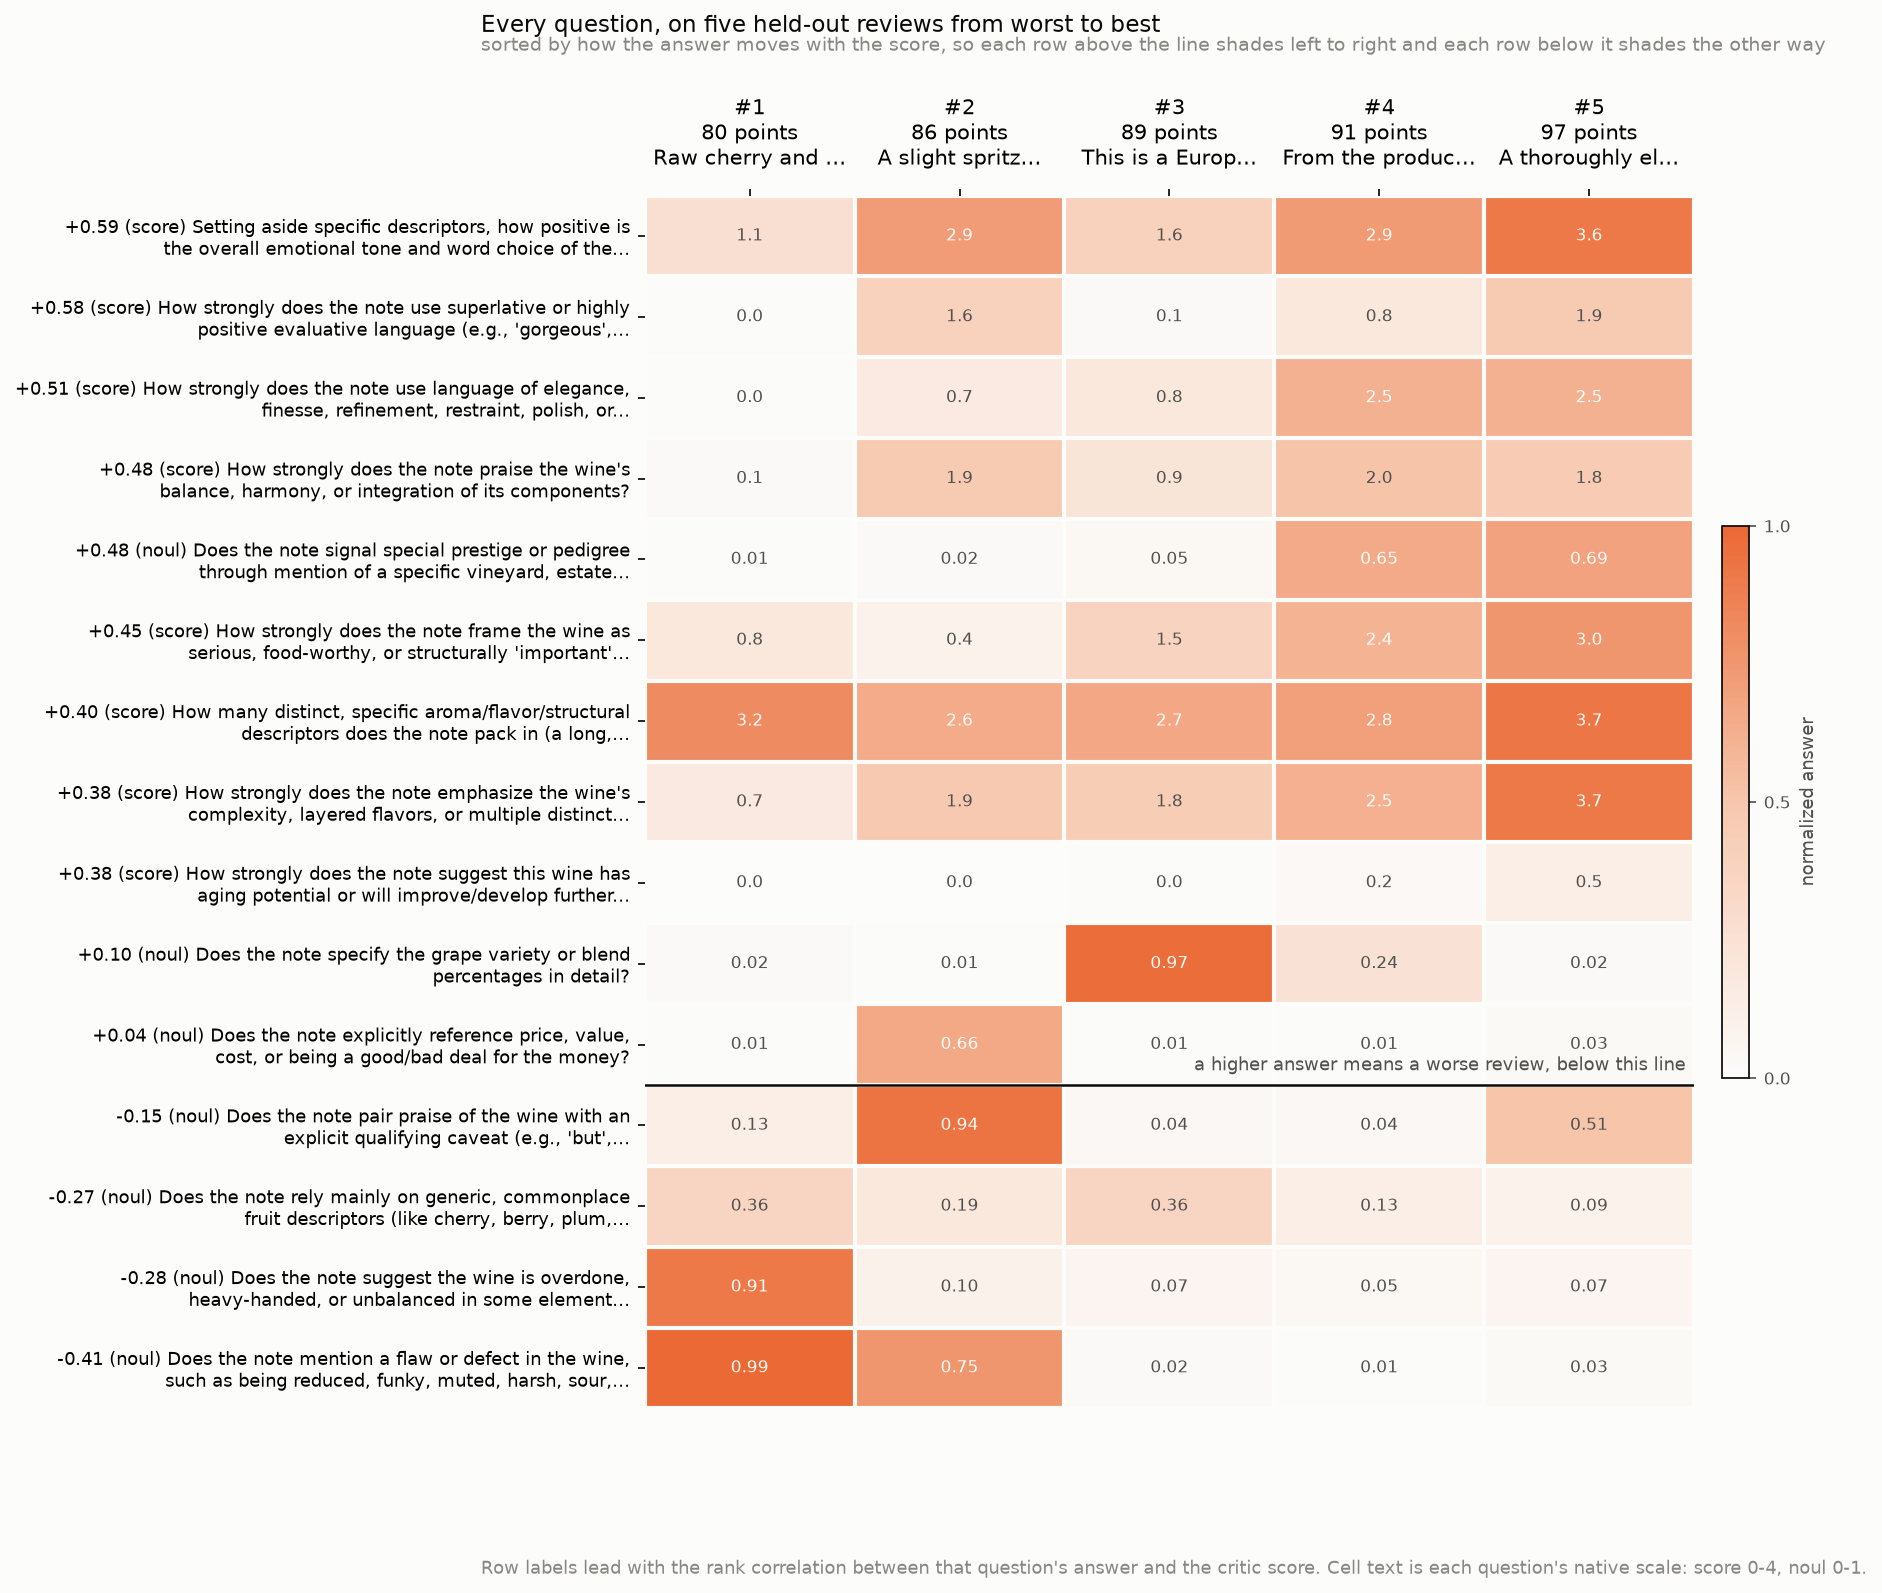
text_features handling, which turns it into word counts. One asks TypeSafe
for the score itself.
That third one is a single Score per row over ten quality bands, from “faulty or
unpleasant” up to “profound”. Ten because ten levels is the most a Score question
takes -
eleven comes back as a server error. Level 0 maps to 80 points and level 9 to 100.
Spreading the bands over the scale that way is not enough on its own, because nothing in
the question says where this publication’s scores actually sit on it. So every answer is
then moved by a single offset, measured on the dev scores. That offset is printed in the
row label, and it is the only thing this shortcut learns from the scores.
Spearman is rank correlation, where 1.0 would put the held-out wines in exactly the
critic’s order. The word-count row is CatBoost’s own text handling, not a tuned
text-regression pipeline. All of this is one dataset and one run of the loop.
Did the autoresearch rounds help?
Both lines plot the error of the question set at the end of each round, starting from the first proposal. The dashed line is the cross-validated dev error, the number every accept and reject decision is made on. The solid line scores the same question set on the held-out rows, which the loop never reads. Each point is the set as it stood when the round closed, so a round that only revised or dropped a question still moves both lines. The feature map says what the questions measure; the error is what tells you whether the rounds after the first proposal made the predictions any better. The axis is tight: everything on it happens inside a fifth of a point, and every shortcut from the table above sits far off the top of it. The dev line runs above the held-out line the whole way, and that is a training-size effect. Each dev fold trains on four fifths of the dev rows, while the held-out number comes from a model that got all 1,200. The two lines move together, so the dev number the loop steers by tracks the held-out number it never sees. The interval under the title comes from resampling the held-out rows, so it says whether the move from round 1 to round 5 is bigger than the noise in 800 rows.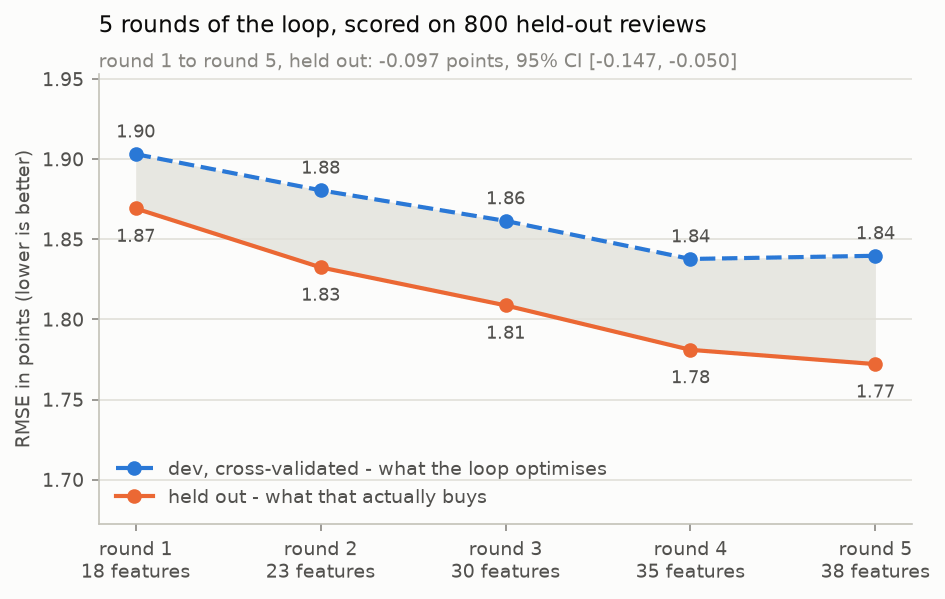
importance share is CatBoost feature importance, normalized so all 38 questions sum to
100%. It is not a share of rows, of questions, or of prediction accuracy. A score question
owns two columns, a mean and a spread, so its two column importances are added back
together before the percentage is printed. note_overall_tone_positivity accounts for
17.4% of the total. The fourth row is a noul: whether the note names a single vineyard or
some other prestige signal is a yes/no fact, so it was asked as one.
Next steps
This run keeps the loop small. Direct extensions:- Screen a candidate before paying to answer it. Treat the proposed question itself as the state and ask nouls about it: can it be answered from the source text, does it mean one thing under its criteria, does it apply to most rows, will it vary across rows. Send only the questions that clear all four with enough confidence.
- Prune correlated features. Measure correlation between encoded columns on the dev rows, cluster the near-duplicates, and keep the clearest or most important question from each cluster.
- Add simple baselines. Compare TF-IDF, character counts, and other structural features on their own, then append them to the discovered columns to measure what each contributes.
- Mix proposer families. Generate candidate batches with Anthropic, OpenAI, Google Gemini, and open-source models, then merge and deduplicate them before any of them reach TypeSafe. Different families should widen the search more than repeated calls to one proposer.
- Compare predictive models and methods. Try linear or elastic-net regression, a support vector regressor, random forests, and recalibration where the downstream output is probabilistic. Check whether the discovered features help outside CatBoost.
- Add an embedding baseline. An embedding turns a note into a few hundred numbers with no
question attached:
sentence-transformers/all-MiniLM-L6-v2runs locally, OpenAI’stext-embedding-3-smallis a hosted call. Append one to the discovered columns and measure whether it carries anything they do not. - Match validation to deployment. Use chronological splits when predicting the future, grouped splits when related rows must stay together, and keep a final test set untouched by both feature discovery and model selection.
- Stop on a plateau. End the loop when cross-validated RMSE stops improving for a fixed number of rounds, or when it reaches a question or request budget.
- Run a longer search in an agent’s Goal mode. Give it an explicit metric, budget, and stopping rule, then let it propose, evaluate, and refine more rounds.
- Check stability. Repeat discovery across seeds or data slices and keep the questions that stay useful, rather than the ones whose importance rests on one split.