

Noul, so each answer is P(true) for one True/False question. In a claims-triage
pipeline, which sorts incoming claims into pay, deny, or send-to-a-human, probabilities
guide the decision. Small changes near a threshold can change which action is taken.
The rubric is 14 Noul questions, and each run is one call that answers all 14. We do
NUM_SAMPLES = 15 repeats per condition, where a condition is one model plus one setting,
and show every probability that came back.
The conditions:
- Non-reasoning LLMs
claude-haiku-4-5andgpt-5.4-mini, at temperature0and the API default. - The same two non-reasoning models in True/False mode: one bare yes or no per question, mapped to 1.0 and 0.0.
- Reasoning LLMs
gpt-5.5andclaude-opus-4-8, which have no temperature dial. - TypeSafe: one
system_onecall over the 14Noulquestions, with a freshuidfield (a throwaway unique value) on each call.
0 too, and on the
judgment calls the models disagree with themselves. TypeSafe’s mean per-question
probability standard deviation is 0.0102, below all LLM probability conditions here.
Its covered answers span 0.43 to 0.53, crossing a 0.5 decision threshold.
We also turn probabilities from 0.30 through 0.70 into an explicit uncertain outcome
for human review. The final illustration maps TypeSafe probabilities to these actions
while keeping the underlying probabilities visible.
Setup
TYPESAFE_API_KEY, ANTHROPIC_API_KEY, and OPENAI_API_KEY.
This run uses jev-latest on the production API, sampled on 2026-09-11.
The state: an auto-insurance claim, as JSON
One claim with a few borderline calls built in:- The loss happened at a track-day event (the policy excludes “track/competitive driving”), but in the parking lot while the car was stationary, not on the circuit.
- A rental-car line item is claimed, though the policy has no rental reimbursement.
- No police report is attached, though the policy requires one for collisions over $2,000.
- An auto-triage note already marks the claim “approved, pay full amount” before any human review, and without withholding the deductible.
json.dumps(CLAIM) in the prompt; TypeSafe
takes the structure as the state directly.
The rubric: 14 Noul questions
One key -> question entry per row, phrased so a yes means the thing we are checking for
is true. That keeps every row comparable: each model’s probability and TypeSafe’s noul
measure the same thing.
How we ask
Each LLM call is one prompt holdingjson.dumps(CLAIM) and all 14 questions. The model
returns a JSON object mapping each question’s key to a probability. Calls route to
Anthropic or OpenAI by model name: non-reasoning models take a temperature (0 or the
API default), reasoning models think first and take no temperature.
The non-reasoning models also run a True/False variant: they answer each question with a
bare yes or no, which we map to 1.0 and 0.0. This forces a hard decision and shows what
these models do when they cannot leave any mass in the uncertain middle.
The TypeSafe call is one system_one request over the same claim and the same 14 Noul
questions. Each answer’s noul is P(true).
Every query also gets a fresh uid, a throwaway unique value that changes each run while
leaving the claim and rubric unchanged. It appears in the LLM prompt and as an extra field
in the TypeSafe state. This setup cannot separate sensitivity to the irrelevant field
from variation that would occur on identical requests.
Note: despite the “ONLY a JSON object” instruction,Each helper returns the answer, an estimated cost, and the round-trip latency.claude-haiku-4-5wraps nearly > every reply in a```json ... ```fence that strictjson.loadsrejects > (the other models return bare JSON). The helper peels the fence; a reply that still fails > to parse becomes a parse failure, counted but not scored.
Experimental Conditions
Experiment Grid
- A check mark is one condition, run 15 times. A dash is a combination that was not tested.
- The default column sends no temperature argument: non-reasoning models use the API default, and reasoning models and TypeSafe run without a temperature setting.
- Yes/no answers map to
1.0/0.0. - Temperature
0is the usual advice for repeatability, so we compare it with the API default.
NUM_SAMPLES = 15 repeats per condition. Each repeat has its own cache key and
counts as a distinct draw, and the cache (json_cache.json) ships with the cookbook, so
re-rendering reuses it and spends no API calls. Delete the cache to sample live again.
Cost + speed (per rubric query)
Costs below use the historical price assumptions in Setup, including thespeed_latest
rate for TypeSafe. They are not verified jev-latest prices or current billing amounts.
One row is one full 14-question rubric call. time/call and cost/call average the 15
calls, and the vs ts_noul columns divide by the TypeSafe figures.
Plot: every sample as a heatmap
How to read it:- Outer row group: the question.
- Inner row: the condition.
- Column: one full rubric call.
- Cell color: red is a higher P(yes), green is lower. For the risk questions, a red cell is one the rubric flagged.
typesafe_noul varies most on covered (0.43 to 0.53) and exclusion (0.53 to
0.62). Some LLM rows vary at temperature 0 too. Conditions disagree on judgment calls.
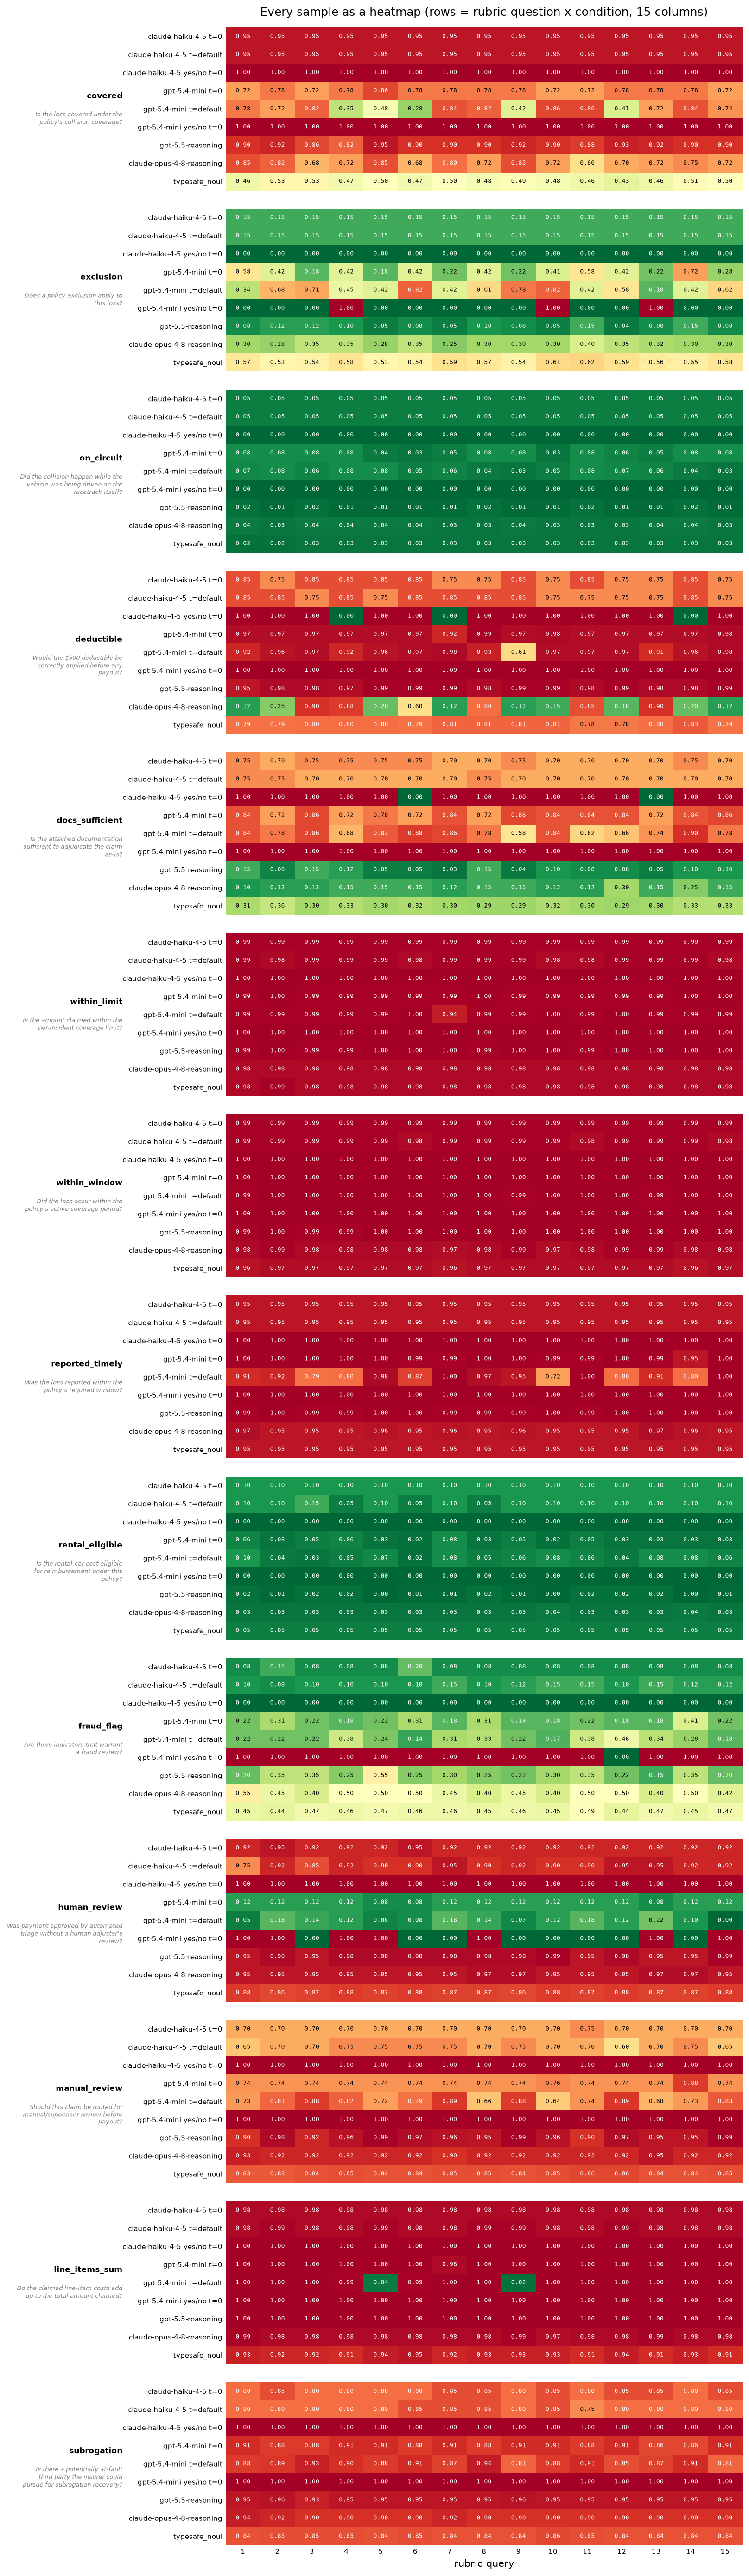
exclusion, rental_eligible, fraud_flag, and manual_review shift
across samples or disagree across models. TypeSafe’s covered row crosses 0.5; its
other 13 questions stay on one side of that threshold throughout this run.
Allow an uncertain decision instead of forcing yes or no
With a threshold of0.5, probabilities 0.49 and 0.51 cause opposite actions even
though both express substantial uncertainty. The application can instead return:
nobelow0.30;uncertainfrom0.30through0.70, including both boundaries;yesabove0.70.
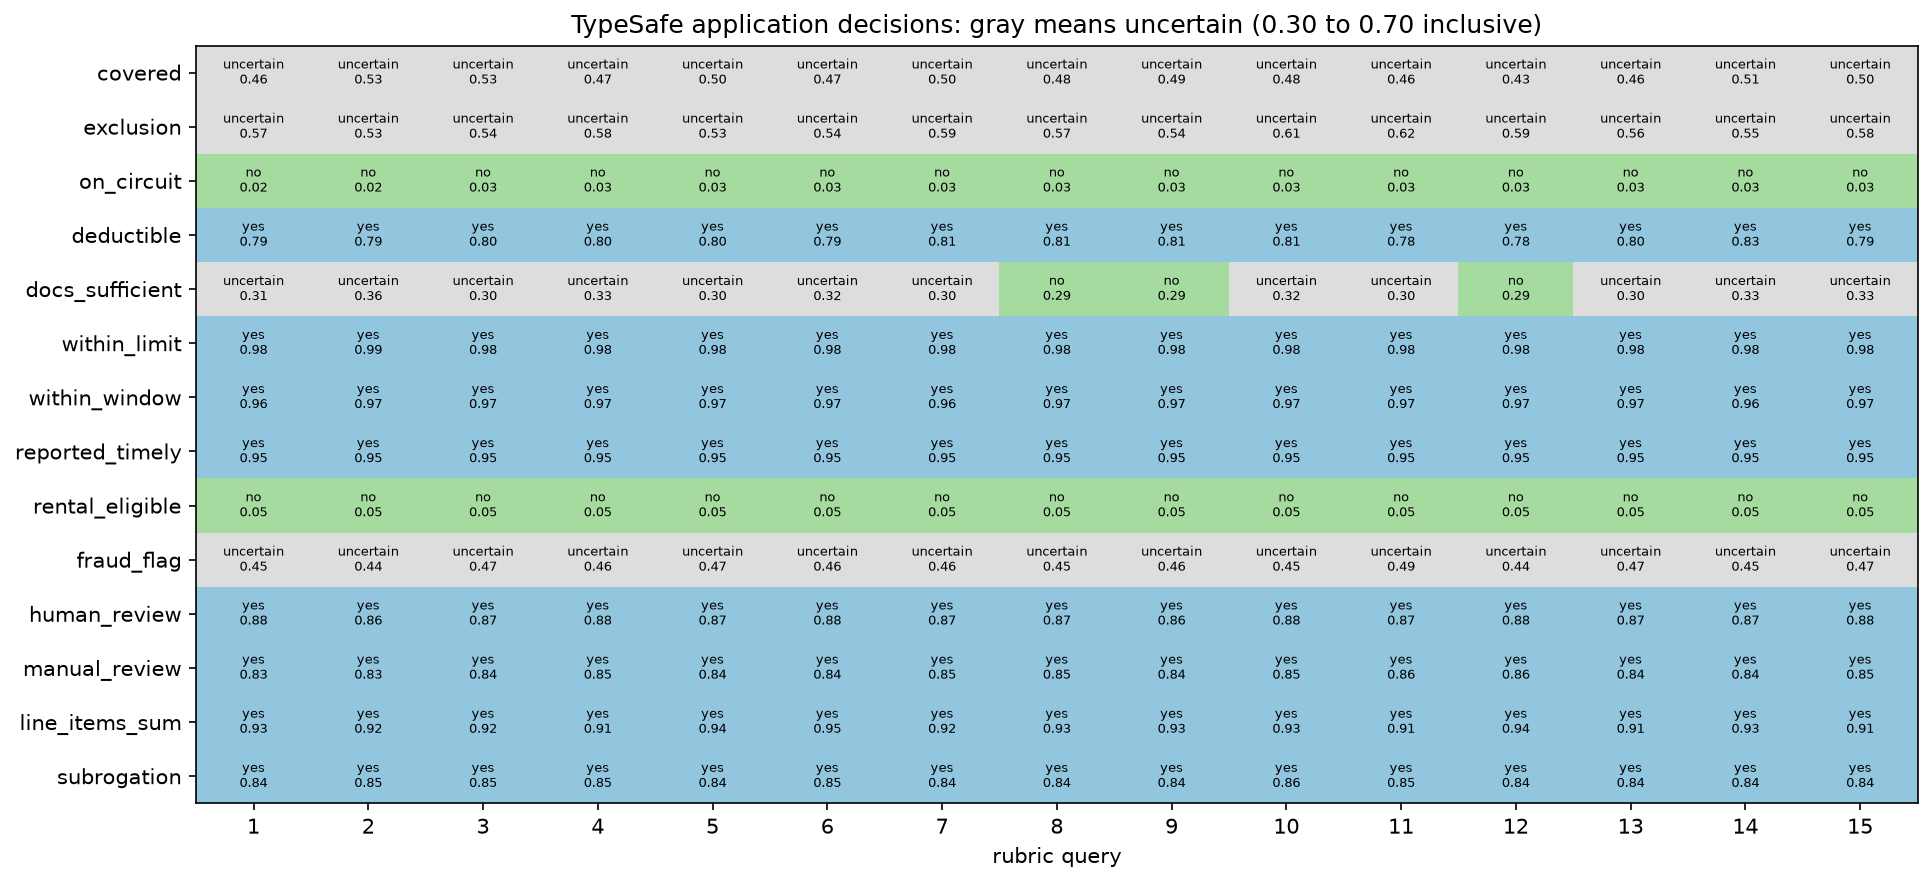
0.5 without issuing opposite automatic
actions. It has edges of its own, though. A value near either outer boundary can still
move between uncertain and yes or no. The model is no more deterministic for it, and
an automatic decision that clears the band is not shown to be correct.
Open it in the TypeSafe playground
The link below opens the same claim and rubric in the playground: one claim, the same 14Noul questions, and TypeSafe jev-latest. It omits the changing uid field used above.