

Choice, so each answer is one label from a fixed set. In a moderation pipeline
that label is the routing decision: remove or leave up, escalate or auto-resolve, send to
the threat, spam, or general queue. When the label wobbles from one run to the next, the
same post routes to different places for no good reason.
The rubric is 8 Choice questions, and each run is one call that answers all 8. We do
15
repeats per condition, where a condition is one model plus one setting, and plot every
label that came back.
The conditions:
- Non-reasoning LLMs
claude-haiku-4-5andgpt-5.4-mini, at temperature0and the API default. - Reasoning LLMs
gpt-5.5andclaude-opus-4-8, which have no temperature dial. - TypeSafe: one
system_onecall over the 8Choicequestions, with a freshuidfield (a throwaway unique value) on each call, matching the noul cookbook setup.
0.60; otherwise
the result is uncertain and goes to human review. TypeSafe’s agreement then rises to
99.2%, with automatic labels on 74.2% of answers. We show the raw outputs and apply the
same threshold to LLM probability conditions, keeping abstentions and changes visible.
Setup
TYPESAFE_API_KEY, ANTHROPIC_API_KEY, and OPENAI_API_KEY.
This run uses jev-latest on the production API, sampled on 2026-09-11.
The state: a borderline user post, as JSON
The post below is built to sit on the fence. The language is heated and insulting, aimed partly at one person and partly at the argument and the community. It carries an off-platform invite (a link pulling people to another site), one prior strike on the account, and four user reports, and the threat-like wording is never cleanly phrased. There is no single obvious answer here, and that is the point: small wording differences should not randomly move the same post between enforcement paths. The LLMs getjson.dumps(POST) in the prompt. TypeSafe gets the Python dict directly.
The rubric: 8 Choice questions
Each question has a key, a line of instructions, and a fixed label set. The labels
within a question are mutually exclusive (exactly one applies), and each carries a
short description. TypeSafe returns a picked choice plus a probabilities
distribution over the labels. The LLMs are asked to use the same label sets, which
keeps every row comparable.
How we ask
Each LLM call is one prompt holdingjson.dumps(POST), all 8 questions, and every allowed
label. There are two answer formats. In distribution mode the model returns one JSON object
per question with a probability on each label. In single-pick mode it returns one bare
label per question, and our analysis puts all the probability mass on that label.
The TypeSafe call is one system_one request over the same post and the same 8
Choice questions, returning one distribution per question.
Every query also gets a fresh uid, a throwaway unique value that changes each run while
leaving the post and rubric unchanged. It appears in the LLM prompt and as an extra field
in the TypeSafe state. This setup cannot separate sensitivity to the irrelevant field
from variation that would occur on identical requests.
Each helper returns the answer, an estimated cost, and the round-trip latency.
Experimental Conditions
Experiment Grid
- A
✓marks a condition tested with 15 repeats; a—marks a combination that is not tested. - The default column sends no temperature argument: non-reasoning models use the API default, and reasoning models and TypeSafe run without a temperature setting.
- Single-pick conditions return one label per question.
- Temperature
0is commonly suggested for repeatability, so it is compared with the API default.
NUM_SAMPLES = 15 repeats per condition. Each repeat has its own cache key and
counts as a distinct draw, and the cache (json_cache.json) ships with the cookbook, so
re-rendering reuses it and spends no API calls. Delete the cache to sample live again.
Cost + speed (per rubric query)
Costs below use the historical price assumptions in Setup, including thespeed_latest
rate for TypeSafe. They are not verified jev-latest prices or current billing amounts.
One row is one full 8-question rubric call. time/call and cost/call average the 15
calls, and the vs ts_choice columns divide by the TypeSafe figures. The LLMs run in a
16-way pool.
typesafe_choice has a mean round-trip latency of 114ms. The LLM conditions
range from 826ms to 13.0 seconds per call under the concurrency settings above.
Plot: every sample’s decision as a heatmap
How to read it:- Outer row group: the question.
- Inner row: the condition.
- Column: one full rubric call.
- Cell text: the application decision plus the probability on the top label.
- Cell color: the label’s position within that question, so the same color all the way across a row means the same decision every time.
- Gray
uncertain: the top probability is below0.60, so the case goes to human review. - Hatched
n/a: the reply did not parse into usable labels (a parse failure). - Blank rows are just spacers.
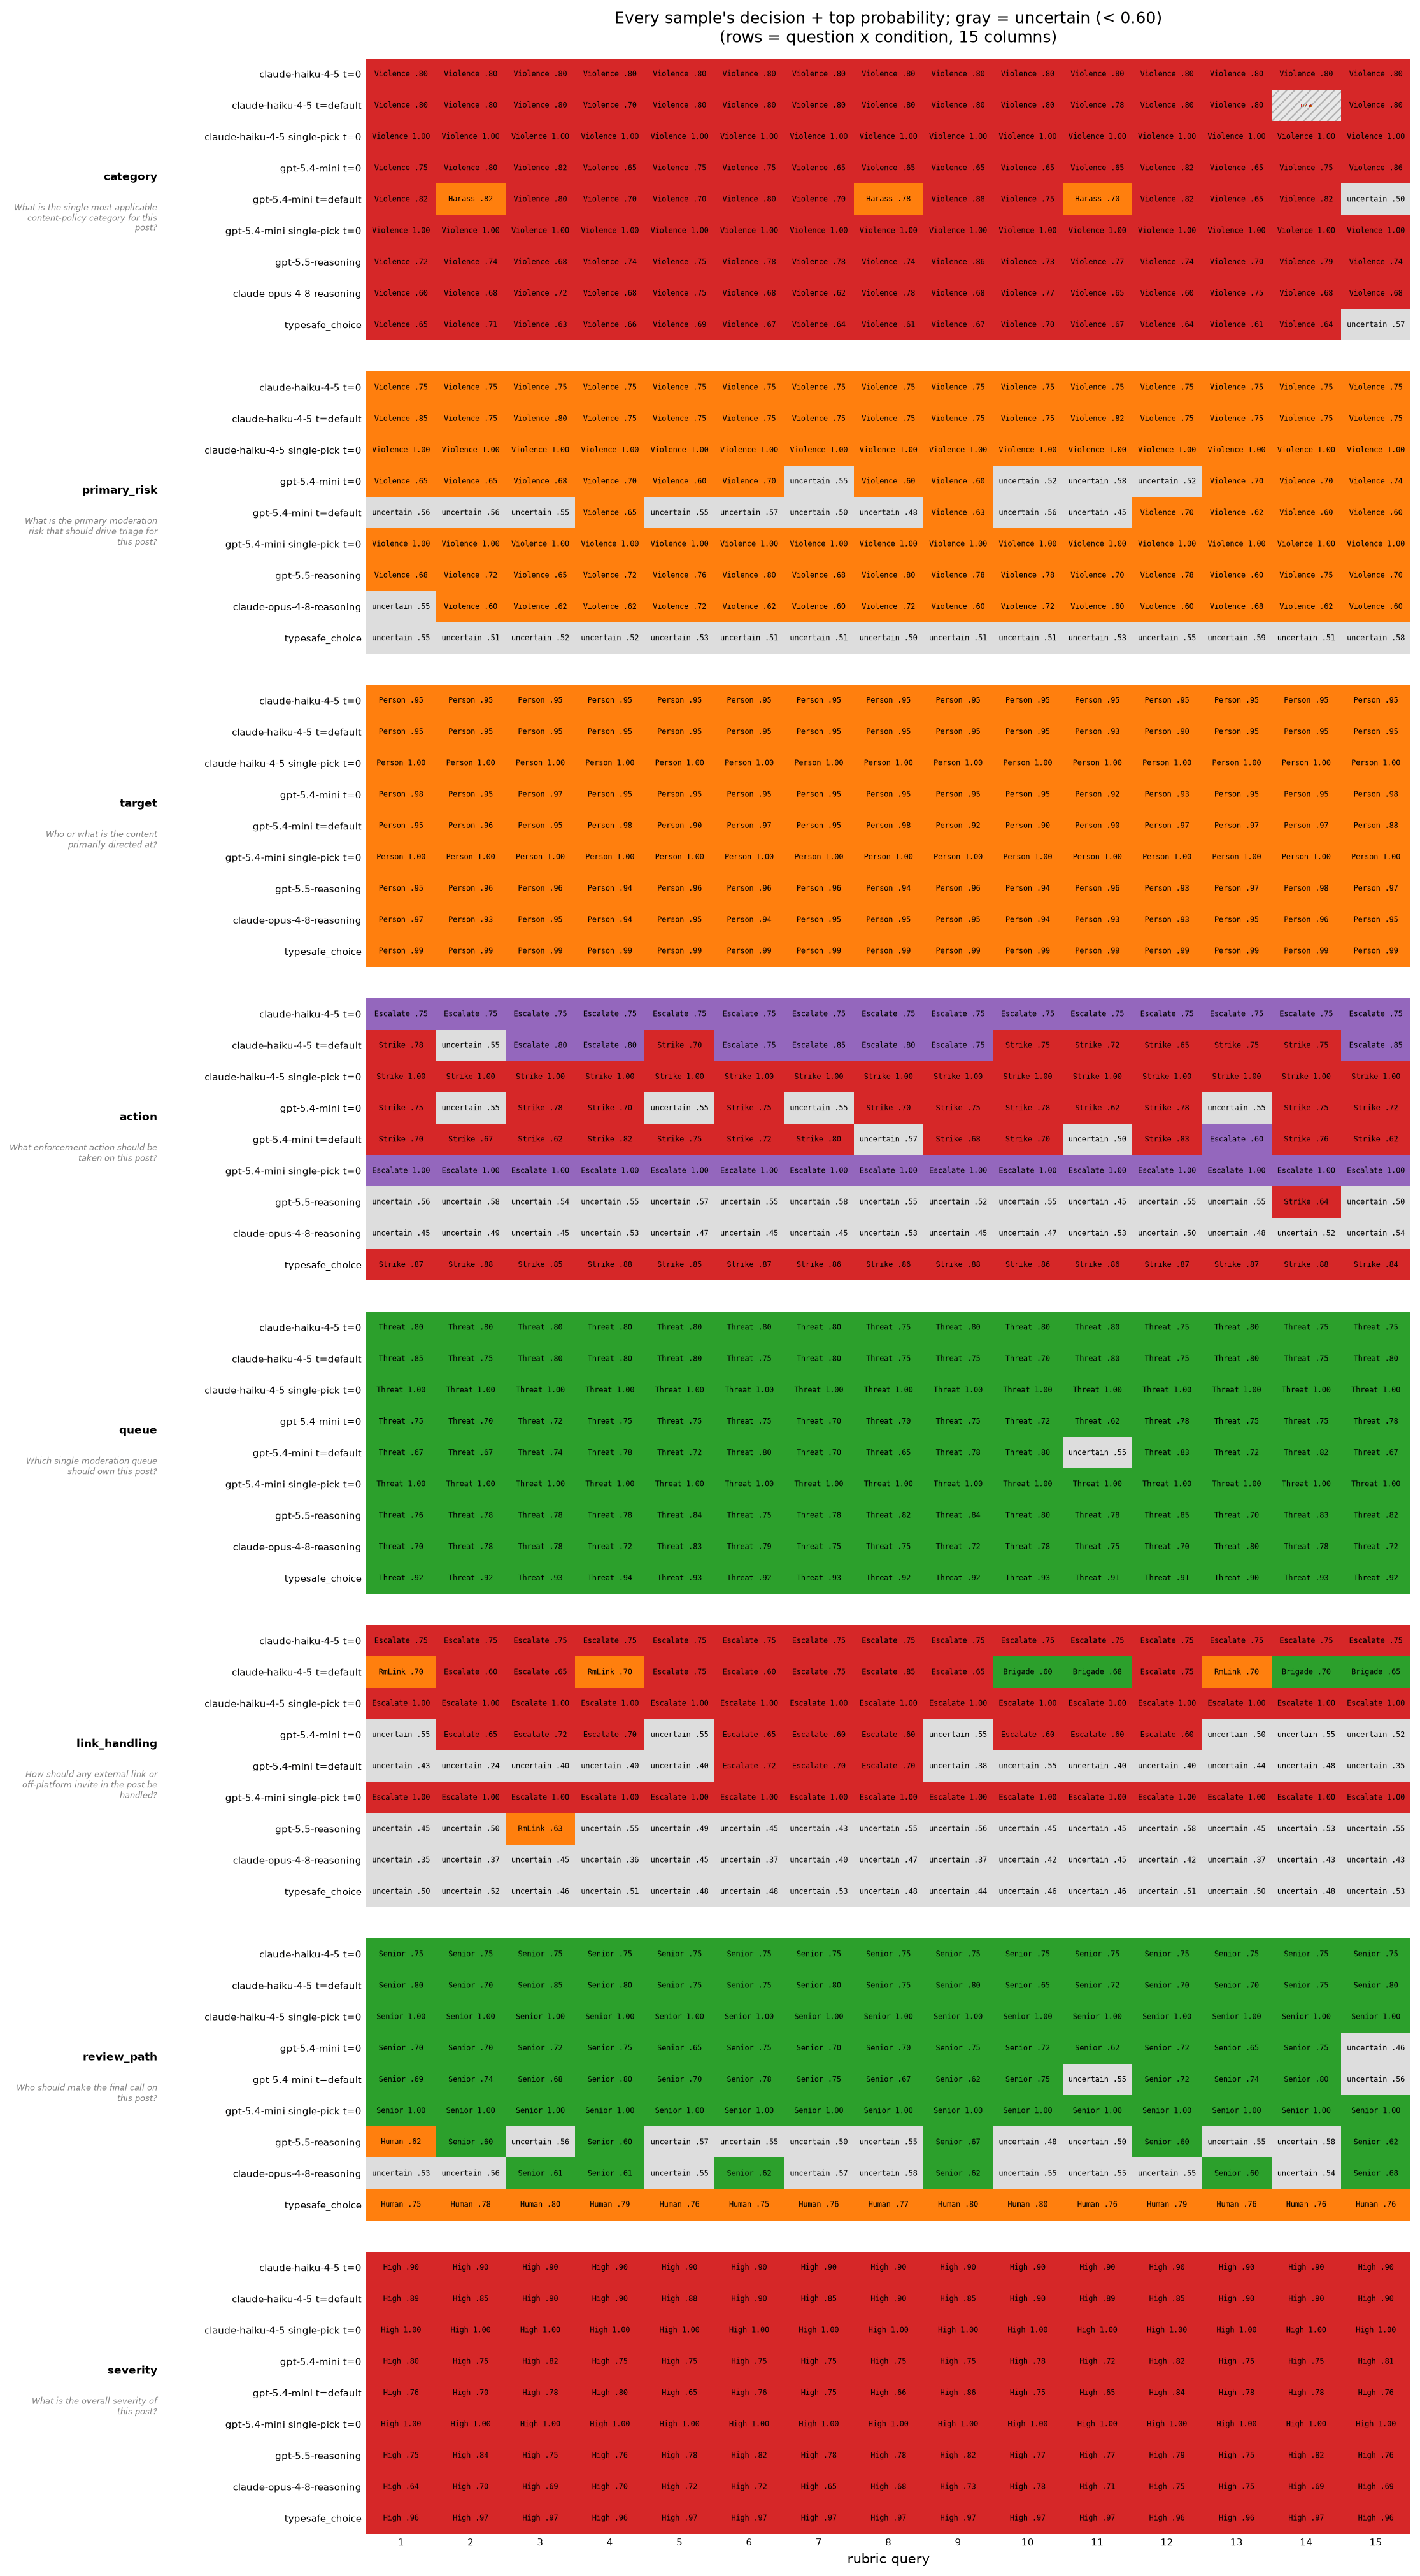
target reads Person and severity reads High across
the board. The borderline ones split across conditions: category, primary_risk,
action, review_path, and link_handling. Some conditions also flip within their
own 15 repeats. Before abstention, TypeSafe changes its top label on primary_risk
(Harassment 11 times, Violence 4 times) and link_handling (RmLink 8 times, Brigade 7
times). Both rows now show uncertain throughout because their top probabilities are
below 0.60.
Probability std dev
This looks at the full probability vectors, not just the picked label. For each condition we collect all 15 distributions for every question, take the standard deviation of each label’s probability across the repeats (how much it moves from run to run), then average those std devs over all labels and questions. We also report the single largest label std dev, and count parse failures separately. The table compares every probability-output LLM condition against TypeSafe. The single-pick rows are left out, since they emit hard labels rather than probability distributions.0.0098 and a max single-label std
dev of 0.0515. Haiku at temperature 0 has a lower mean std dev of 0.0012. The other
five LLM probability conditions range from 0.0245 to 0.0543, about 2.5x to 5.6x
the TypeSafe mean. Small changes can still switch the top label when two labels are close.
Plot: decision agreement with an uncertain outcome
Returnuncertain when the top probability is below 0.60. For each probability-output
condition and question, count the most common application decision, including uncertain,
and divide by all 15 draws. Parse failures count against agreement. Each bar averages the
score over all 8 questions, with the highest agreement first.
Single-pick LLM conditions are excluded because they provide no uncertainty estimate.
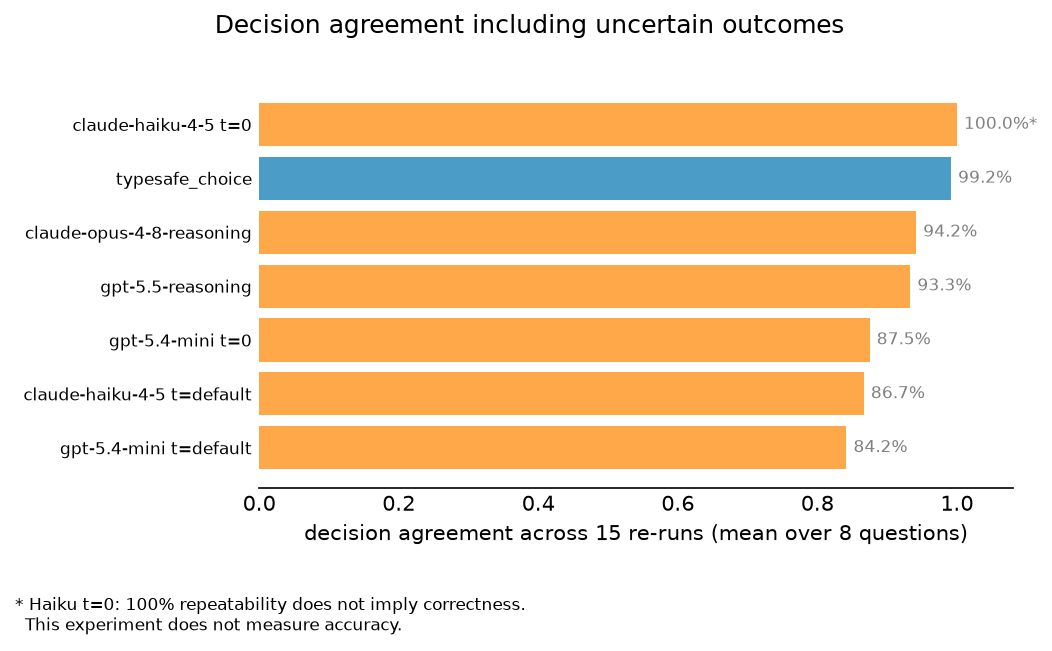
0.60 rule, Haiku at temperature 0 scored 100%. TypeSafe scored 99.2%, and
the other LLM conditions landed between 84.2% and 94.2%. TypeSafe returned uncertain on
25.8% of answers and acted automatically on the other 74.2%; Haiku at temperature 0 never
abstained. These percentages measure repeatability only. The table below sets raw agreement
and abstention rates next to the policy agreement in this chart.
Let uncertain probabilities produce an uncertain decision
A small probability change can swap two close labels. The application does not have to act on the winner: returnuncertain when the top probability is below 0.60, and send
that case to a human. At exactly 0.60, select the top label. This uses the returned
probabilities, not the API’s separate confidence field, and adds no model calls.
The threshold is an illustrative application policy, not a calibrated guarantee or a
threshold chosen to maximize this run’s agreement. Choose production thresholds using
labeled examples and the cost of incorrect actions and human review.
We apply the same rule to every probability-output condition. Single-pick LLM responses
have no probability estimate; their synthetic one-hot vectors cannot measure uncertainty,
so they are excluded from the agreement chart and table.
policy agree counts uncertain as a decision; parse failures count against agreement.
automatic is the share of all answers that select a label. conflicts counts questions
with more than one concrete label across the repeats, ignoring abstentions. These measures
describe repeatability and how often the application acts, not whether its actions are
right.
TypeSafe’s agreement rose from 90.8% to 99.2%. Of the answers, 25.8% were uncertain and
74.2% automatic. primary_risk and link_handling came back uncertain on every repeat;
category alternated between Violence and uncertain, crossing the action threshold on
some repeats and not others. No question produced two different concrete TypeSafe labels.
None of this shows accuracy or superiority: Haiku at temperature 0 had 100% agreement
here, with no abstentions.
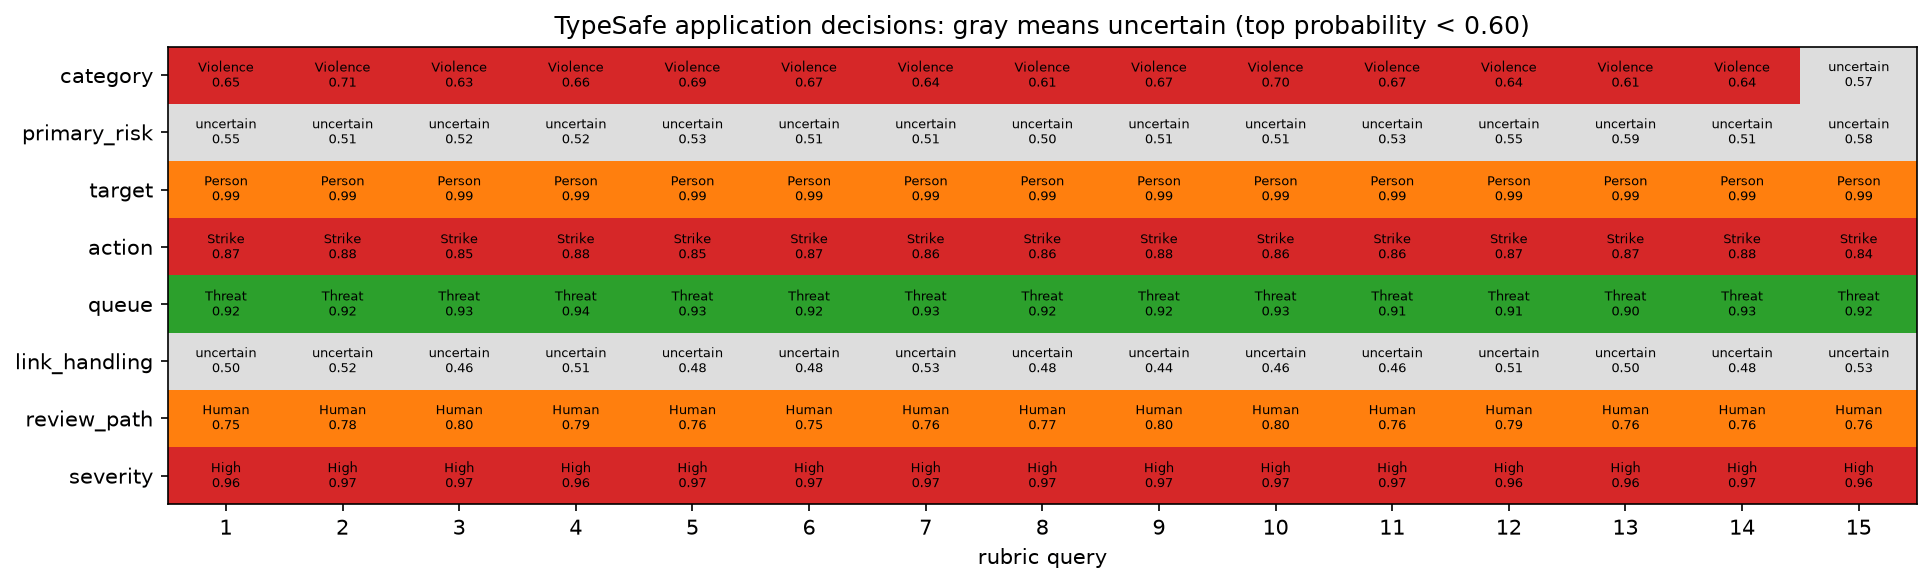
0.60 can still move
between a concrete label and uncertain. The probability statistics and the table’s raw agree column still report the original model outputs.
Open it in the TypeSafe playground
The link below opens the same post and rubric in the playground: one post, the same 8Choices, and TypeSafe jev-latest.